GovSpend
Grew engineering from 2 to 13 and launched six AI products; customers named the four primary ones as deciding factors in $10M+ of new sales and renewals.
Open case studyEngineering leader. I build teams and ship AI products at scale.
Grew engineering from 2 to 13 and launched six AI products; customers named the four primary ones as deciding factors in $10M+ of new sales and renewals.
Open case study
What I build with my own hands - an agent that runs incident response end to end.
Open case study
Change the Game. My animation framework took it from freezing phones to 60 FPS and unblocked launch.
Open case study
Platform for Google events
Open case studyEngineering leader. I build teams and ship AI products at scale.
GovSpend · Government procurement intelligence SaaS
Lattice · HR and performance management SaaS
Little Cinema Digital · Interactive streaming platform
Izllo · Marketplace startup
Earlier: AKQA (Audi USA), 2015 - 2017 · The Barbarian Group (Samsung US), 2015
How can I make myself replaceable?
My management philosophy comes down to one question I ask myself: how can I make myself replaceable? People grow most when they have clarity on what success looks like, the autonomy and trust to find their own way through, and consistent, pointed feedback along the way. My engineers would describe my style as collaborative, structured, trusting and autonomous. I am a hands-on coach early on, then I deliberately step back so people can grow into ownership.
Four tech leads I coached now own their roadmaps and operate without me in the room. At GovSpend I promoted two engineers to Staff and one to engineering manager. That is the measure I actually care about.
The hardest part of working this way is the discipline to refrain from stepping in, especially when you can see something about to go wrong and you know exactly how to fix it. Letting someone experience it and then coaching them through the reflection is almost always more effective than solving it for them. The risk is stepping back too early, before somebody is ready, and I guard against that by being explicit about what success looks like and staying closely observant at the start.
When somebody wants a decision from me, I ask for four things: the problem, the options they considered, the tradeoffs, and their recommendation. I call it the Decision Stack. People stop bringing me problems and start bringing me their call. They own the decision, and I weigh in if I see a risk they missed.
Telling whether a team is actually succeeding comes down to four things, and they build on each other. Clarity: everyone individually understands the why behind the mission. Metrics: measuring cause and effect, so we understand our impact and can realign when we need to. Synergy and ownership: an environment where everyone feels responsible for the outcome, with no egos and no gatekeeping, just a shared urgency to succeed together. And delivery: a target date is the focal point that closes the loop, because knowing the when informs both the strategy and the urgency.
Once a team has clarity, metrics and ownership, I rarely have to chase the date. They hit it on their own.
I evaluate engineers on two pillars. Impact, which is reliability, performance and scalability. And communication and leadership, which is alignment, clarity and knowledge-sharing. At the higher levels I expect engineers to design systems that other teams build on. I wrote these into a career matrix with four levels: Associate, Engineer, Senior and Staff. Using AI well is part of what I expect at every level.
On team structure, I aim for roughly thirty percent senior, forty percent mid and thirty percent junior. It creates growth paths without sacrificing delivery on complex work. I keep a primary and a secondary on every project so no single person is a point of failure. I change the structure as the business changes, and I keep each engineer's growth in mind when I do.
Across a larger org, I made RFCs mandatory for significant work and anchor my reviews on production risk, scale and maintainability: what happens if this fails, how do we mitigate it, what will this cost in production? I lean on the experts on my team. My job is to set things up so the right decisions get made, even when I am not in the room.
I lead engineering teams that ship. Most recently I was Director of Software Engineering at GovSpend, where I grew engineering from two people to thirteen across four product tracks and launched six AI products. Customers named the four primary ones as deciding factors in more than ten million dollars of new sales and renewals. Before that I managed a ten-person platform team at Lattice, led the team behind a no-code streaming-site builder at Little Cinema, founded a startup, and was a web engineer at Google.
With people, I start by learning what drives each person and where they want to grow. Then I set them up and step back. At GovSpend I promoted two engineers to Staff and one into engineering management. I am prouder of that than of anything I have shipped.
I still write code. I want to know the work I am asking my team to do. At GovSpend I built our AI evaluation layer on top of Mastra - golden datasets, blinded LLM-as-judge and human review, CI/CD gates - and on my own time I build agents like the AI Chief of Staff in the work section.
I have been taking things apart since I was six, starting with toys and old computers. I still like finding out how things work.
Outside work I dance, travel, play piano, train in martial arts, and try something new as often as I can.
Five pieces on TypeScript's error messages, static typing, and what to do with an engineer who is failing in the wrong role. Read over thirty thousand times.
30,000+reads on Medium
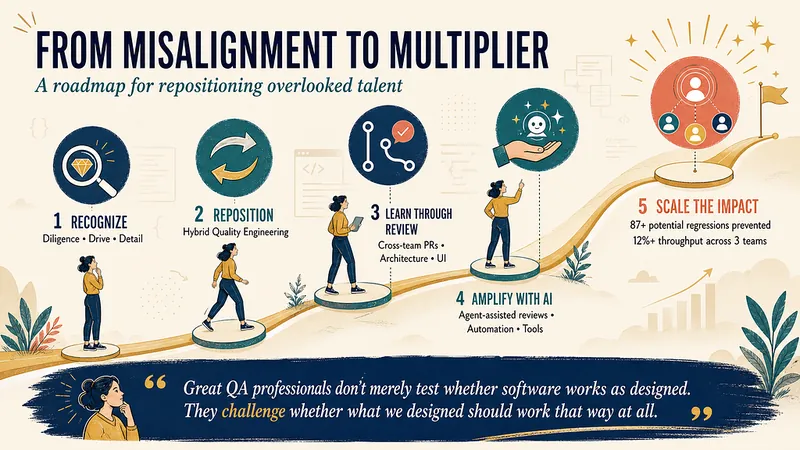 Poor Performer? You Might Just Have Them in the Wrong RoleI once managed a junior engineer who was struggling in a conventional software-development position.
 The TypeScript Guide I Wish I Had
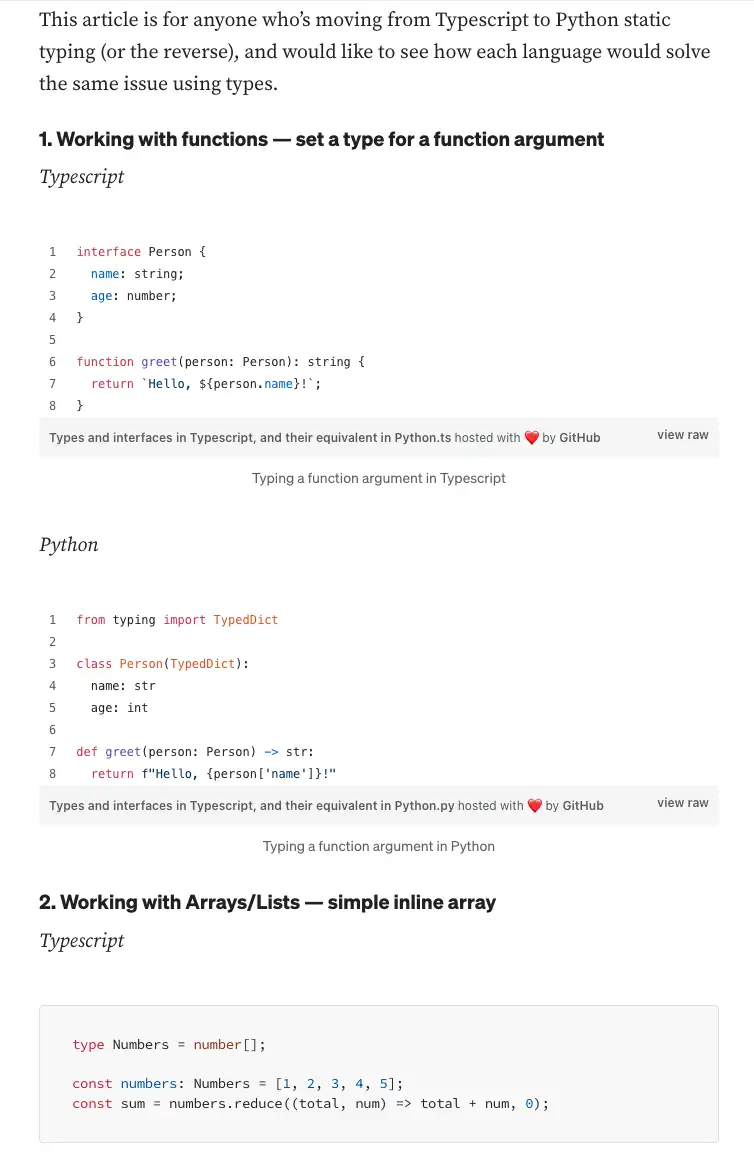
 A Cheat sheet for Python and Typescript static typing
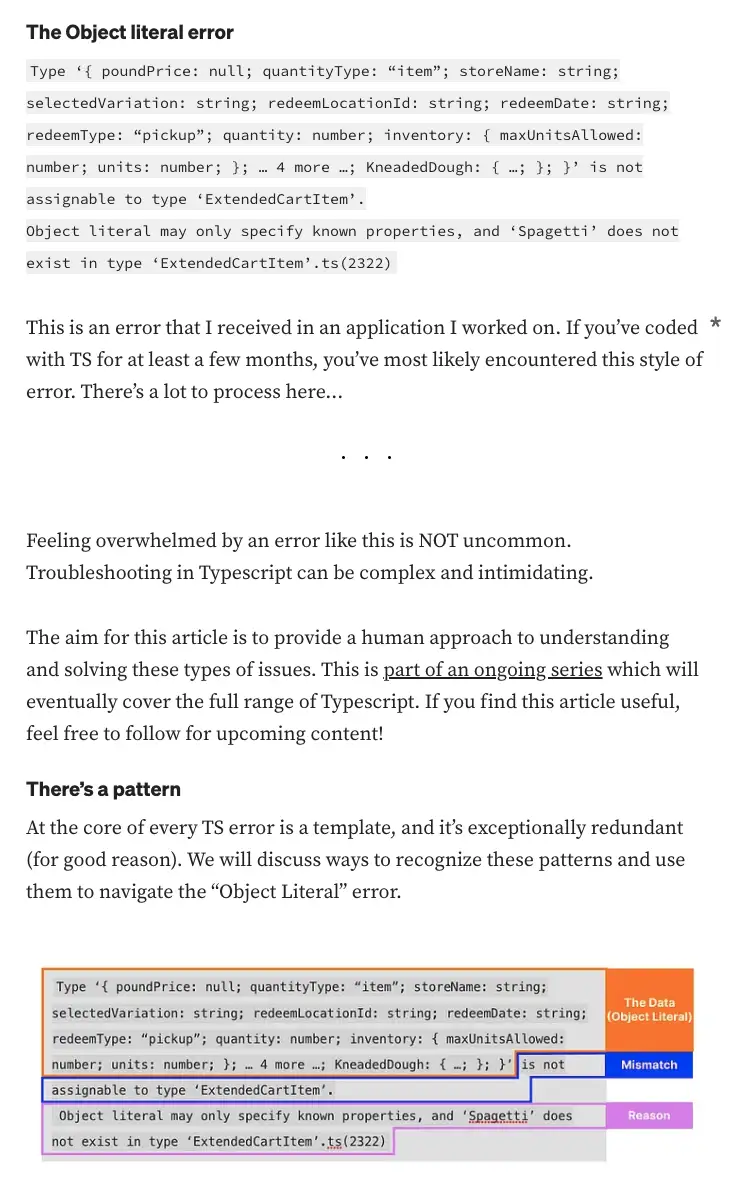
 Conquering a complex error in TypescriptHow to read and understand the Object Literal error
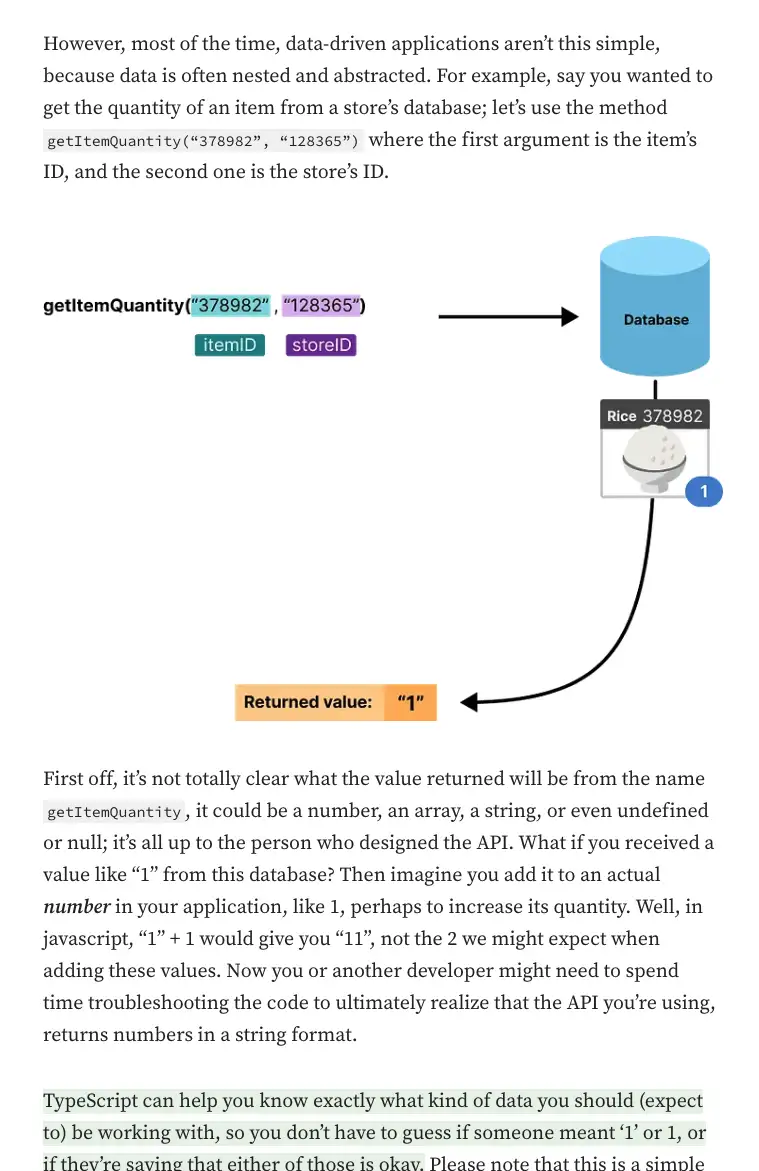
 How To Read Errors in TypeScriptTypeScript can be riddled with errors and warnings, for seemingly every little thing. Take this function for example:
Hiring an engineering leader? Let's talk. I am open to Engineering Manager, Senior Engineering Manager and Director roles. Email is the most direct, my resume is a PDF you can download, and you can also find me on LinkedIn or GitHub.
Grew engineering from 2 to 13 and launched six AI products; customers named the four primary ones as deciding factors in $10M+ of new sales and renewals.
GovSpend sells procurement intelligence to companies that sell to government. I joined in January 2024 as Engineering Manager for the web application, with two engineers. When I left in July 2026 as Director of Software Engineering, engineering was thirteen people across four product tracks, and it had launched six AI products. Customers said the four primary ones helped them decide to buy or renew.
Grew engineering from 2 to 13 across AI Products, Web Applications, Federal Data and Greenfield, in five time zones. Managed nine engineers and an engineering manager with three reports.
Two engineers promoted to Staff and one to engineering manager. Four tech leads coached to own their roadmaps. Engineer onboarding cut from 5 months to committing code in the first week.
Six AI products launched. Customers named the four primary ones (AI Search, MCP integration, Opportunities, AI Notebook) as deciding factors in more than $10M of new sales and renewals, per Commercial's win and renewal surveys.
Sprint commitment completion from 22% to 96% in five months. Escaped production bugs down 71% and feature delivery up 78% in five months.
I grew the team from two engineers to thirteen, organized into four tracks: AI Products, Web Applications, Federal Data and Greenfield, spread across five time zones. As the org grew past what one manager could hold, I promoted one engineer into engineering management and managed that manager and their three reports alongside nine engineers of my own. I coached four tech leads until they ran their roadmaps without me in the room. Two engineers were promoted to Staff on the strength of work they led.
I cut engineer onboarding from 5 months to new engineers committing code in their first week. Templated onboarding packets written for each engineer, and tickets crafted to help new engineers onboard, took it to 3 months. AI automation and the review memory below took it the rest of the way.
AI made writing code faster. The hard part was making the whole team faster without paying for it later in rework.
One engineer built a Slack app on our MCP server entirely with AI. It demoed well on the happy path. Then it met real users, who could set it up dozens of different ways, and it was verbose, inefficient and unreliable.
When I took over that team's engineering and product, we rewrote it. We set clearer guidelines and split the work into small pieces other engineers could follow, review and give pointed feedback on. The rewrite became a reliable production product.
The lesson I took from it: AI can write the code, but people have to be able to review it. That is also the idea behind the review memory.
It started as a set of agents, one named after each engineer, each keeping the feedback that engineer left on pull requests. It grew into one shared review memory, tagged by team and by section of the codebase, so it knew each area's best practices and how feedback is given there.
Engineers decided what went in. A GitHub app watched for a rocket emoji on a pull request's comment thread. When someone added one, a worker sent that thread's context to the review memory, which embedded it as vectors. When a new pull request came in, it retrieved the past feedback that matched the lines being changed and left its review.
It started with simple changes and over time left good reviews on complex ones too, the way our senior engineers would, at scale. This is separate from the AI Chief of Staff I built for myself. That one works for me; this one worked for the team.
As AI built more of our work, we also made that work easy for people to read. We leaned on dot charts and diagrams so people could quickly see how things worked.
When I arrived, most of the team's time went to fixing bugs, and 22% of committed work landed on its target date. We moved estimation into deeper grooming, so engineers understood the work before they started it, and reviewed burndown against target dates at every sprint kickoff without moving the targets. Five months later sprint commitment completion was 96%.
In the same period, QA and project management helped me link every production bug to the ticket that introduced it, and we tracked the share of features that shipped with no bug inside a month. Escaped production bugs fell 71%, and the capacity that freed up raised feature delivery 78%.
We launched six AI products: AI Panel, AI summaries on detail pages, AI Notebook, the MCP integration, AI Search and Opportunities. AI Panel and the detail-page summaries came first and set the foundation. Customers named the other four as deciding factors in their purchases and renewals.
Our Model Context Protocol server let customers search GovSpend's procurement data in plain language, from inside Slack and their own AI tools, without logging in to GovSpend. I worked directly with Microsoft's, Amazon's and four other enterprise customers' security teams to bring the MCP server in line with their standards.
I built the team that had Opportunities ready in three months. It builds a profile of each customer with AI and surfaces the contracts, bids and grants that fit their market, so they get insight without having to search. It became a multimillion-dollar offering.
We shipped AI Search on a platform serving 10,000+ customers, including Fortune 100 companies and federal agencies, over 15 years of procurement data from thousands of state and local agencies and 19 federal datasets. It used multi-agent orchestration over hybrid vector and BM25 retrieval. Customers who used it renewed at a 21% higher rate than customers who did not.
We A/B tested two ways of showing results: a chat view and interactive visual results. The visual version drove about 28% more engagement.
We cut end-to-end query latency at P95 from 10 seconds to 2 by tuning reasoning effort and agent memory against evaluation results rather than by feel.
We did not build our own eval framework. I chose to adopt Mastra for agent orchestration, with its evals built in, rather than build one: it had a proven track record, it fit our TypeScript stack, and the evals came with it. I built the evaluation layer on top of it. Golden datasets were approved by Product and QA, an eval interface connected to our MCP server, answers were scored by blinded LLM-as-judge and human review, and CI/CD gates scored every release on quality, latency and cost. Those gates caught an MCP regression that our unit tests missed.
A customer's founder and CEO, on the MCP integration my team shipped, as GovSpend published it:
"I've been using the MCP to work with GovSpend data, and it's unbelievably productive and accurate. For me, it brings the K-12 project intelligence I need into one place so I can stay current without bouncing between systems or manually piecing things together. It's beyond time saving, it ensures we key in on quality over quantity with our knowledge of K-12 projects."
The original post
the customer testimonial, as published